
A frequentist 95% confidence procedure covers the fixed parameter in 95% of repeated samples under its stated model. Once a particular interval has been calculated, that parameter is either inside it or outside it. The 95% describes the procedure's coverage.
A probability statement about the parameter after observing data requires a Bayesian model, including a prior. Neither interpretation should be silently substituted for the other.
An original calculation
Suppose 36 independent observations come from a normal distribution with unknown mean and known standard deviation 12. Their sample mean is five. The standard error of the mean is 12/√36 = 2.
Using the standard normal 97.5th percentile, approximately 1.96, the two-sided 95% interval is:
5 ± 1.96 × 2, or approximately [1.08, 8.92].
The known standard deviation and normal independent observations make the usual normal interval appropriate here. If the standard deviation were estimated from this normal sample, a t procedure would account for that estimation. Other settings need their own justification rather than automatic substitution of 1.96.
What more observations change
Under the same independent model and known standard deviation, quadrupling sample size halves standard error. It does not remove bias, repair a wrong target or make dependent observations independent.
For a simple illustration, suppose observations have common variance σ² and every distinct pair has covariance ρσ². Then:
Var(sample mean) = σ² [1 + (n−1)ρ] / n.
Positive dependence can leave much more uncertainty than the independent formula suggests. This is a specific joint-covariance model, not a universal estimate for any time series.
Work through the dependence change
Keep the sample mean of five and marginal standard deviation of 12. Now change the model: the observations are jointly normal with a common mean, and every distinct pair has known correlation 0.10. This is an original hypothetical exercise, not an estimate of market-data correlation.
With 36 observations, the variance of the mean becomes:
144 × [1 + 35 × 0.10] / 36 = 18.
Its standard error is √18 ≈ 4.24, rather than two. Because the mean is normal and this covariance structure is known, the corresponding interval is 5 ± 1.96 × √18, approximately [−3.32, 13.32]. The wider interval follows from a changed model; the observed mean has not changed.
| Assumed structure | Observations | Variance of the mean | Standard error |
|---|---|---|---|
| Independent, known standard deviation 12 | 36 | 4 | 2 |
| All distinct pairs have known correlation 0.10 | 36 | 18 | About 4.24 |
| All distinct pairs have known correlation 0.10 | 144 | 15.3 | About 3.91 |
In the last row, four times as many observations does not halve the standard error. Under this particular model, the variance is 144 × [0.10 + 0.90/n]; a shared component remains as n grows.
You can express the second row's variance as the variance of a mean of eight independent observations: 144/8 = 18. That is a variance-equivalent sample size for this estimator and model. It does not mean you should discard 28 rows, or that eight is an effective sample size for every statistic computed from these observations.
Try the follow-up: What must you revisit if 0.10 was estimated rather than known? The uncertainty of that estimate and the suitability of the covariance model become part of the problem. Plugging an estimate into the calculation does not by itself establish exact 95% coverage. A covariance specification alone also does not establish normality.
For the basic mean-interval and coverage interpretation, see the NIST statistical handbook. The correlated calculation above is a separate worked extension under the explicitly stated joint-normal model.
Selection changes the question
If you inspect many specifications and show only the interval attached to the most favorable estimate, the selection procedure affects interpretation. The usual single-analysis coverage statement does not automatically apply to the selected winner.
Record what was tried, which data selected the procedure and whether a final evaluation remained untouched. A narrow interval after extensive undocumented searching is not automatically strong evidence.
A concise spoken explanation
“Under independent normal observations with known standard deviation, the standard error is two and this procedure gives about [1.08, 8.92]. Its 95% label is repeated-sampling coverage. I would revisit the procedure if the observations were dependent or the specification had been chosen after inspecting these same data.”
The research lab focuses on evaluation design, comparisons and honest interpretation. It is not a comprehensive mathematical-statistics text. For its timing discipline, read the leakage checklist.
The statistics interview preparation page helps distinguish the explanation and evaluation skills practiced in the lab from the additional theory your target role may require.
For a separate worked task, use why pooled success rates can reverse subgroup comparisons. If you need to choose a resource afterward, compare pooled-rate preparation: arithmetic diagnostic or research project?.
Read before choosing
Open the actual pages.
7 sample pages, including complete explanations. No email address or account required.
Open the PDF previewPreview page 4 of 7. Use Enlarge page for a closer view. When the page is focused, use left and right arrows to change pages.
Read the complete free sample as text (7 pages)
Text from the same public sample shown above. Use the page images or PDF for diagrams, equations and original layout.
Sample page 1
QUANT FINANCE PLAYBOOK PYTHON / VALIDATION / RESEARCH Quant Research Project Lab A reproducible synthetic study, three investigations, and a research memo you can defend. QUESTION -> PROTOCOL -> EVIDENCE Keep the failed experiment. EDITION 01 / ORIGINAL PRACTICE & WORKED EXAMPLES
Sample page 2
QUANT FINANCE PLAYBOOK RESEARCH PROJECT LAB Edition 01 / September 2026 02 HOW TO USE THIS BOOK Quant Research Project Lab Ten chapters, three worked capstone investigations, two executable Python scripts, recorded base and extension results, editable worksheets and an annotated research memo. Assumes basic Python and introductory statistics. Read the model before reading the answer. Try each exercise on paper, keep your first attempt, and use the explanation to diagnose the first step that needs repair. Original educational examples The exercises and candidate scenarios are original teaching material. They are not leaked employer questions, employment outcomes, or descriptions of actual trading performance. Sources identify public guidance and further reading; cited organizations do not endorse this publication. Edition 01 September 2026. Independent educational material. This edition has not been reviewed by an identified industry practitioner. Use the supplied companion files alongside the chapters, and distinguish fictional examples and synthetic results from your own evidence. FINAL-SEGMENT MSE / SEED 20260923 Stable 1.161 0.903 Reversed 1.342 2.501 Gray: training-mean baseline. Blue: frozen linear fit. Lower error is better.
Sample page 3
QUANT FINANCE PLAYBOOK RESEARCH PROJECT LAB Edition 01 / September 2026 03 CONTENTS Your route through the work 4 01 / The question before the model 6 02 / Build a world you can inspect 8 03 / Put every value on a time axis 10 04 / Make the simple alternative hard to ignore 12 05 / Freeze a procedure, not just a file 14 06 / Keep the result that did not work 16 07 / Give the decision an accounting rule 18 08 / Three investigations to complete 24 09 / Write a memo that survives a skeptical reader 26 10 / Defend the work and release it cleanly
Sample page 4
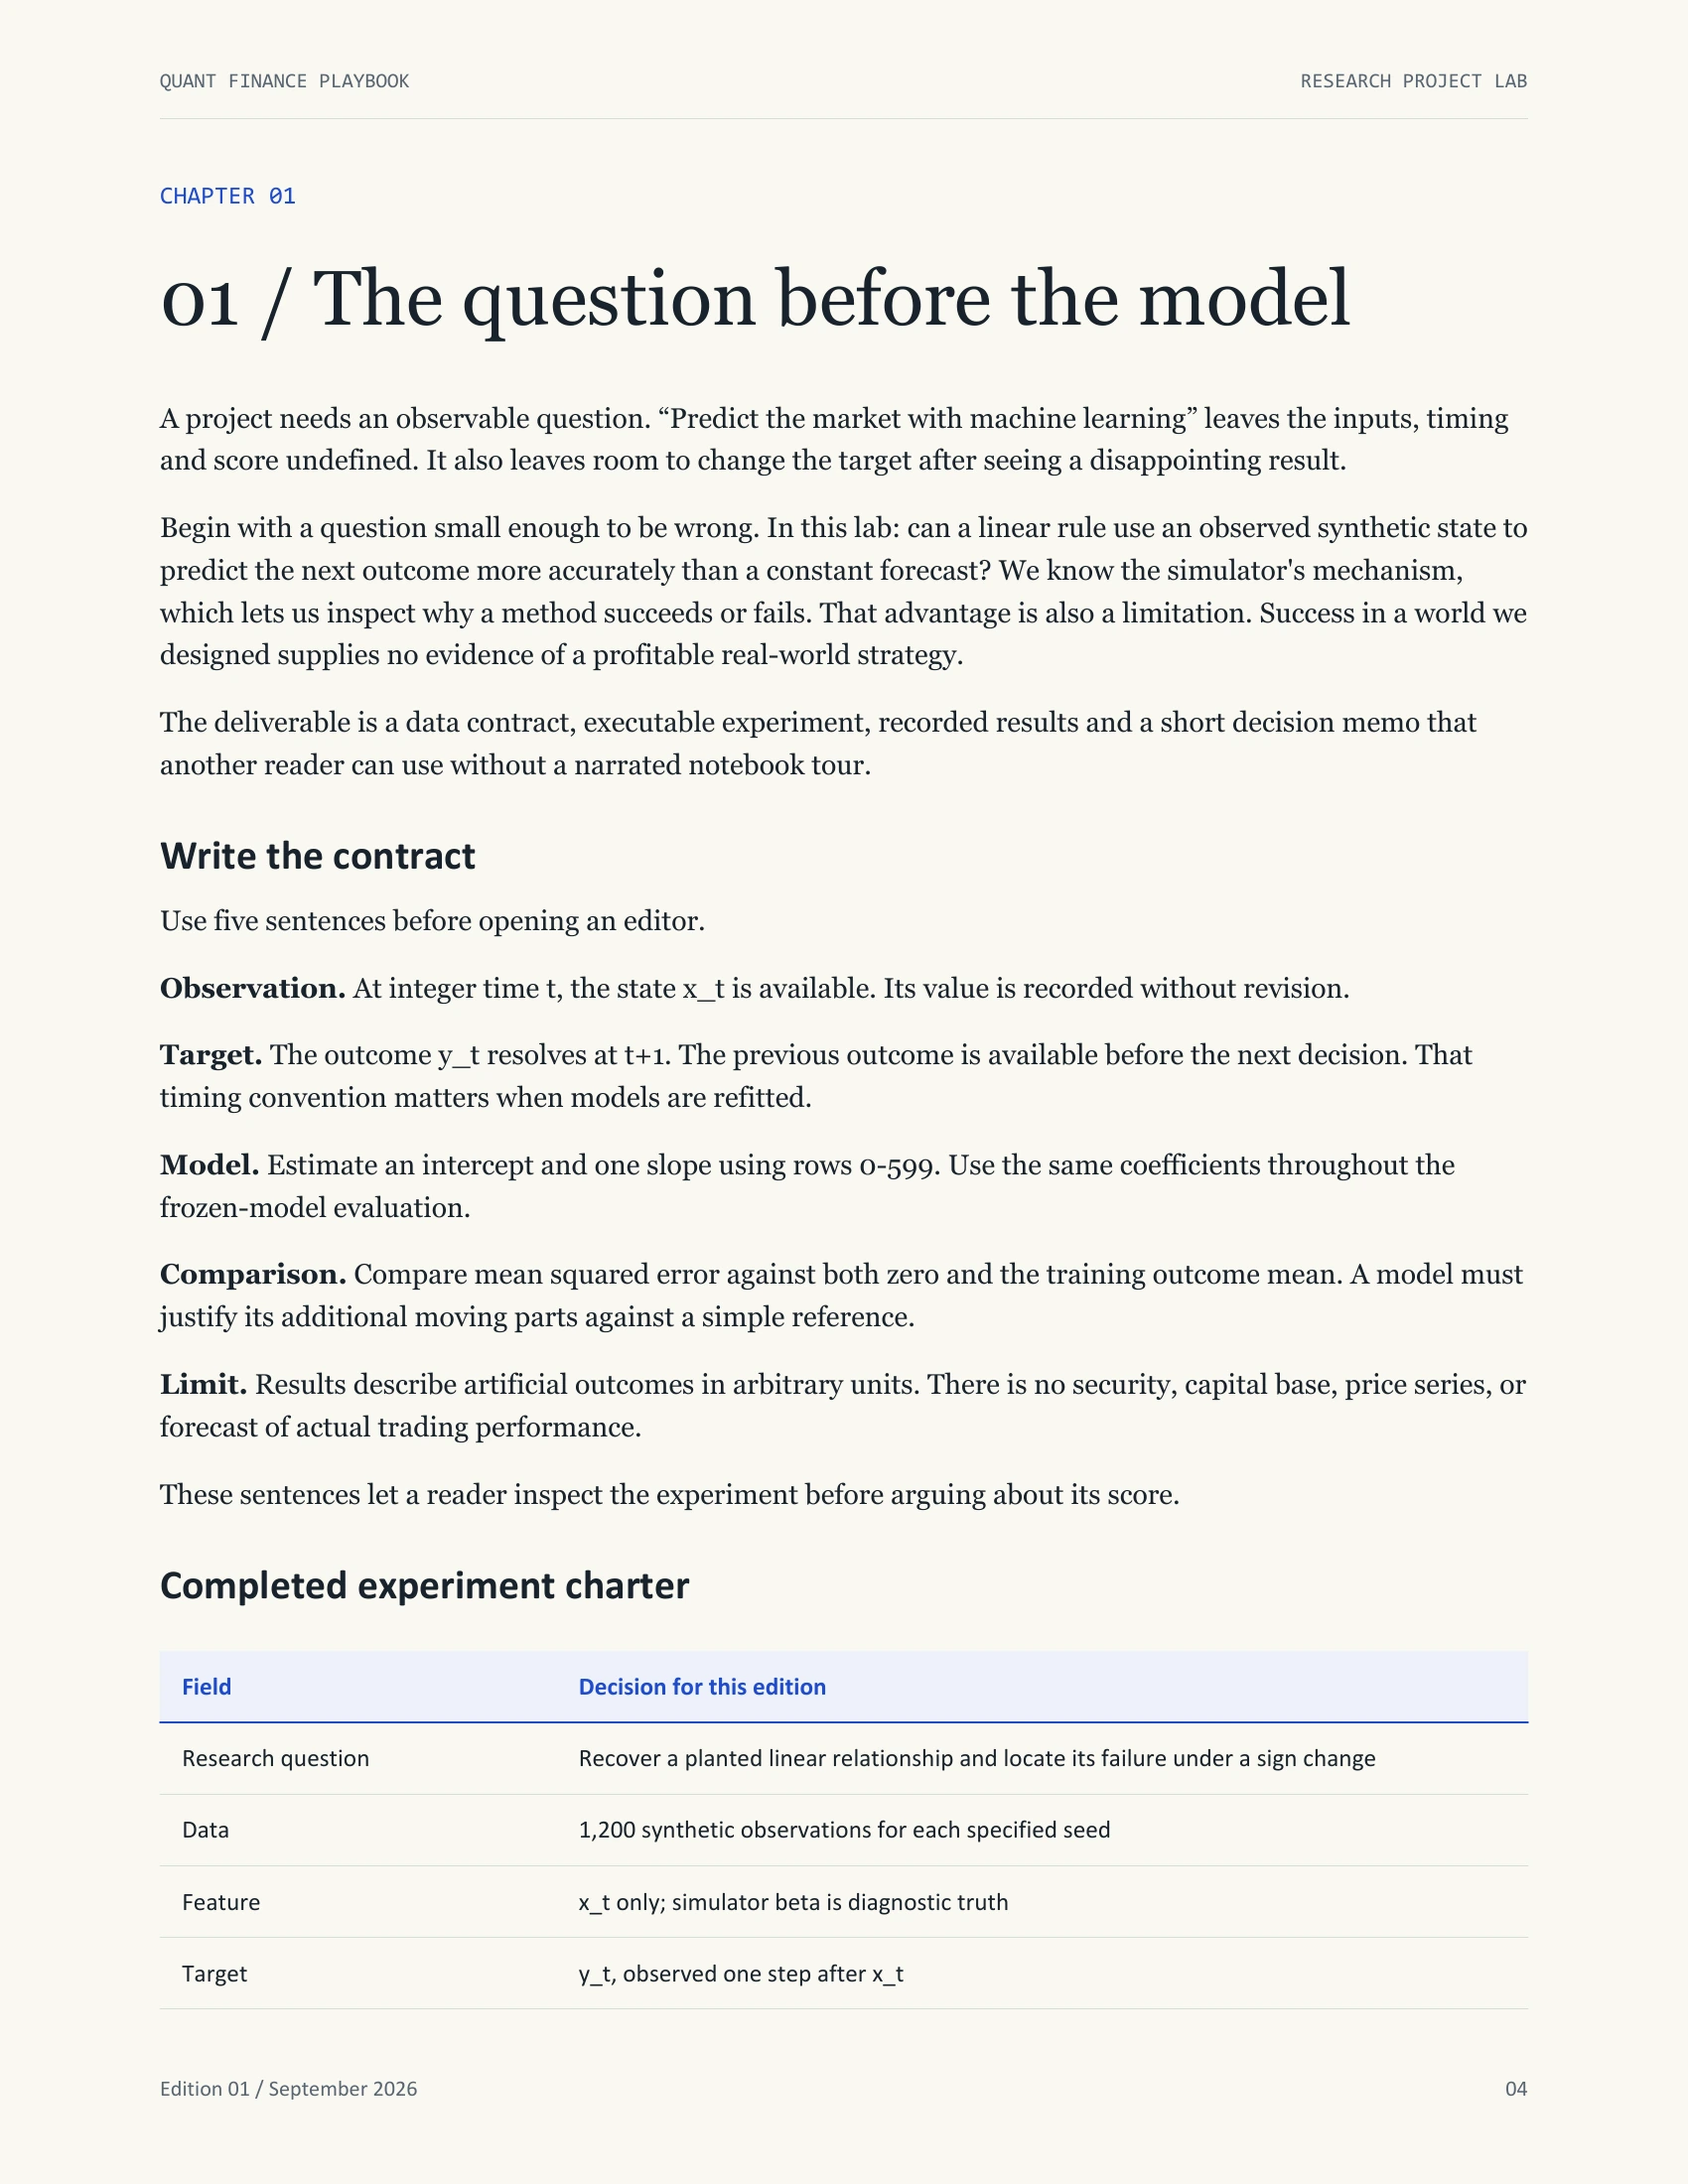
QUANT FINANCE PLAYBOOK RESEARCH PROJECT LAB Edition 01 / September 2026 04 CHAPTER 01 01 / The question before the model A project needs an observable question. “Predict the market with machine learning” leaves the inputs, timing and score undefined. It also leaves room to change the target after seeing a disappointing result. Begin with a question small enough to be wrong. In this lab: can a linear rule use an observed synthetic state to predict the next outcome more accurately than a constant forecast? We know the simulator's mechanism, which lets us inspect why a method succeeds or fails. That advantage is also a limitation. Success in a world we designed supplies no evidence of a profitable real-world strategy. The deliverable is a data contract, executable experiment, recorded results and a short decision memo that another reader can use without a narrated notebook tour. Write the contract Use five sentences before opening an editor. Observation. At integer time t, the state x_t is available. Its value is recorded without revision. Target. The outcome y_t resolves at t+1. The previous outcome is available before the next decision. That timing convention matters when models are refitted. Model. Estimate an intercept and one slope using rows 0-599. Use the same coefficients throughout the frozen-model evaluation. Comparison. Compare mean squared error against both zero and the training outcome mean. A model must justify its additional moving parts against a simple reference. Limit. Results describe artificial outcomes in arbitrary units. There is no security, capital base, price series, or forecast of actual trading performance. These sentences let a reader inspect the experiment before arguing about its score. Completed experiment charter Field Decision for this edition Research question Recover a planted linear relationship and locate its failure under a sign change Data 1,200 synthetic observations for each specified seed Feature x_t only; simulator beta is diagnostic truth Target y_t, observed one step after x_t
Sample page 5
QUANT FINANCE PLAYBOOK RESEARCH PROJECT LAB Edition 01 / September 2026 05 Field Decision for this edition Training 0-599 inclusive Validation 600-899 inclusive Final illustration 900-1199 inclusive Primary score Mean squared prediction error in squared outcome units Baselines Zero and training mean Secondary investigation Bounded positions, turnover costs, one-step delay Failure evidence Worse error than a baseline; unavailable inputs; conclusions sensitive to omitted assumptions Reproduction Python script, recorded version, seeds, hashes, CSV and JSON outputs The “final illustration” was a held-out segment for this fixed experiment. Once this book shows its results, it is no longer unseen evidence for a reader who changes the model after reading them. For your own extension, state that you are exploring this dataset or create a genuinely separate evaluation protocol. A useful project boundary For six available evenings, try this allocation: contract and generator; baselines; time ordering; failure cases; memo; reproduction from the release instructions. Adjust it to the work. If the generator takes longer, reduce the model menu and preserve time to explain the result. Before adding a model or cost assumption, finish the sentence: “This comparison could change my conclusion because…” Exercise: repair the brief Original: “Build an accurate model on a large dataset and use the best result on my resume.” Rewrite it with a target, a decision time, a baseline, and a rule for retaining failed experiments. One defensible answer: “Predict next-step synthetic outcomes from currently observed states; compare a training-only linear fit with the training mean on later rows; preserve all attempted specifications and report the chosen rule's failure under a changed generator.” This does not promise that a model will win. It promises an inspectable investigation. Your first artifact: a one-page charter naming what you observe, when it is available, what becomes known later, your comparator and the result that would change your conclusion. Mark unresolved assumptions explicitly.
Sample page 6
QUANT FINANCE PLAYBOOK RESEARCH PROJECT LAB Edition 01 / September 2026 06 CHAPTER 02 02 / Build a world you can inspect The lab has two random innovations per row. One moves an observed state; the other adds unpredictable noise to its outcome. Write the mechanism as: x_t = 0.65 x_(t-1) + u_t y_t = beta_t x_t + e_t Both innovations have mean zero and variance one and are independently generated. The initial state is zero. The stationary scenario keeps beta at 0.4. The changed scenario keeps it at 0.4 through row 799, then sets it to -0.4. The sign change is specified in the generator; it is not discovered from actual market data. The coefficient 0.65 gives the feature persistence. A high state tends to be followed by another relatively high state, although the next innovation may reverse it. Because its absolute value is below one, an old shock's effect shrinks geometrically: after k steps, its contribution is multiplied by 0.65^k. What the correct model should learn Conditioning on x_t in the stable scenario gives expected outcome 0.4x_t. A linear model with enough data should estimate a slope near 0.4 and an intercept near zero. It will not predict the independent e_t. Even the oracle forecast has expected squared error one because that is the noise variance. Do not reject a finite-sample error below one as impossible. One is the expected error across repeated draws, not a floor on every realized average. Likewise, a fitted slope of 0.405 is not proof that the true mechanism changed. Estimation varies with the sample. In the long-run stationary distribution, the state's variance solves v = 0.65²v + 1. Thus v = 1/(1-0.65²), approximately 1.732. The outcome variance is 0.4²v + 1, approximately 1.277. A zero forecast therefore has expected long-run squared error around 1.277; the oracle improves it by approximately 0.277. Early rows start from zero rather than from that stationary distribution, so this is a reference calculation, not an exact expectation for every finite sample average. Read the generator before the output Open lab.py and find the generate function. It constructs x first and y second. The order encodes the information structure. The beta value is stored to explain the experiment later; it must never be provided to the fitted forecasting rule. The code uses a local random.Random(seed) instance. Each experiment therefore starts with its own generator state. It does not depend on random calls made by unrelated notebook cells. Recording a seed is useful only when the algorithm and environment are also known. The output records the Python version and script hash; the release run used Python 3.12.14.
Sample page 7
QUANT FINANCE PLAYBOOK RESEARCH PROJECT LAB Edition 01 / September 2026 07 Changing the regime flag does not change the sequence of random shocks for a given seed. It changes how the same state is mapped into an outcome after row 799. This pairing helps isolate the effect of the sign change. It does not produce two independent datasets, so do not count them as independent evidence when discussing uncertainty. Data dictionary Column Meaning Available to model? t Ordered decision index Yes, as an index; this model does not use it as a predictor x Current observed state Yes y Outcome resolving next step Only as a previously resolved training label beta Generator's current signal coefficient No; diagnostic truth All numeric outcome units are arbitrary. Calling 0.27 a “27% return” would invent a denominator and an economic interpretation. A synthetic decision exercise can teach accounting without masquerading as a backtest of a traded instrument. Exercise: change one assumption Suppose u_t has variance four rather than one. Keep e_t variance one and all coefficients unchanged. What happens to the long-run state variance and the oracle error? Solution. State variance becomes 4/(1-0.65²), approximately 6.926. The oracle still removes the conditional mean and leaves e_t, so its expected error remains one. The zero forecast becomes worse because the predictable component has become more variable. A larger percentage improvement need not mean a more sophisticated model; the data-generating problem became easier relative to its noise. Exercise: explain what is missing Name three reasons success here would fail to establish a live trading opportunity. Discussion. We chose a known, simple signal; there is no market impact or order execution; no data licensing, revisions, selection of securities, capital constraints or competition is modeled. Many other answers are valid. State what each omission changes rather than appending a generic limitations paragraph.